A customer service employee has a complaint open in the CRM. The record contains the customer’s name, email address, account number, transaction history and the actual complaint.
The employee asks an approved AI assistant to analyse it and suggest a response.
There is nothing obviously wrong with that request. The employee is allowed to see the record. The AI application is approved. The task is part of the employee’s job.
Yet the model has just received information it probably did not need.
It needed the complaint. It may have needed the product involved and some transaction context. The customer’s actual name, email address and account number were probably irrelevant to the task.
Traditional DLP is not particularly good at making that distinction.
It can determine whether the user is allowed to access the record. It can determine whether the destination is approved. It can block certain types of information from being sent outside the organisation.
What it generally does not ask is whether the recipient needs every field in the data being shared.
That becomes a much more important question when the recipient is an AI model.
The DLP Problem Has Moved Closer to the Data
For years, enterprise DLP has been built around controlling movement.
A file leaves the company. An employee uploads something to a personal cloud account. Sensitive information is copied to a USB device. A document is emailed to an external address.
The security team puts controls around those events.
AI creates a different kind of exposure because the transfer can happen inside an entirely legitimate workflow.
Employees paste source code into coding assistants. Finance teams upload spreadsheets for analysis. Lawyers ask AI tools to review contracts. Security analysts give assistants authentication logs.
In each case, the user may have a valid reason to use the information.
The problem is that the model receives the information in its original form.
Take source code as an example. A developer might paste a configuration file into an AI coding assistant to troubleshoot an error. Buried inside that file could be a database password, API token or internal service credential.
The developer did not intend to share the credential. They may not even have noticed it was there.
A traditional DLP system can detect some of these values and block the request. That is useful, but it leaves the security team with a fairly blunt choice: allow the entire request or block it.
Masking gives you another option.
The configuration can reach the model with the credential removed while the rest of the code remains available for analysis.
The same approach works with customer records.
Instead of sending:
Customer: Ahmed Rahman
Customer ID: 78451236
Email: ahmed.rahman@example.com
Product: Enterprise Email Security
Complaint: Email delivery stopped after a policy change.
the AI system could receive:
Customer: [PERSON_001]
Customer ID: [CUSTOMER_ID_001]
Email: [EMAIL_001]
Product: Enterprise Email Security
Complaint: Email delivery stopped after a policy change.
The model can still understand what happened.
It knows there is a customer, a customer identifier, a product and a complaint. It can analyse the issue and draft a response without being given the customer’s actual identity.
That is a different way of thinking about DLP.
The objective is no longer limited to deciding whether information can leave one security boundary and enter another. The control can sit inside the transaction and change what the receiving system actually gets.
Masking Has to Be Smarter Than Redaction
There is an obvious temptation to solve this with [REDACTED].
That works until the information being removed is part of the context the model needs.
Suppose an organisation wants an AI assistant to review a contract between two companies and identify conflicting payment terms.
Removing every company name and every number would protect the data. It would also make the analysis considerably less useful.
Pseudonymisation is more practical:
[COMPANY_001] will pay [COMPANY_002] AED 2.4 million
within 30 days of the effective date.
The model does not need to know which real companies are involved to compare the payment obligations.
The same idea becomes useful when relationships matter.
If a case contains:
Ahmed reported the issue to Sara.
Sara escalated the issue to the account manager.
Ahmed received a response two days later.
you can replace the identities while keeping the relationship intact:
[PERSON_001] reported the issue to [PERSON_002].
[PERSON_002] escalated the issue to the account manager.
[PERSON_001] received a response two days later.
The model can still follow the sequence.
That is where AI data masking becomes more interesting than simple redaction. The objective is to remove the value that identifies the real-world entity while retaining enough structure for the model to do its job.
Different data needs different treatment.
An email address might simply be removed. A customer identifier may need a stable token because it appears in several records. A financial value might need to remain because the model is being asked to analyse revenue. A secret should generally disappear completely.
The policy needs to understand the task.
A blanket rule such as “mask all PII” will protect data, but it can also make legitimate AI use unnecessarily difficult.
The Hard Part Is Deciding What the Model Actually Needs
A DLP engine already knows how to look for patterns such as credit card numbers, email addresses, phone numbers, national identifiers and other structured data.
Enterprise AI needs more than that.
A confidential project name may not match a useful pattern. A paragraph describing a pending acquisition may contain no obvious identifier at all. Internal architecture information may be sensitive even though it looks like ordinary technical text.
The detection layer therefore needs to combine deterministic inspection with contextual classification.
There is another security consideration here that is easy to miss.
You should not send a confidential document to another public AI service simply to determine whether the document contains confidential information.
For sensitive workloads, classification itself may need to happen inside the organisation’s controlled environment or through a model with appropriate security and privacy controls.
Once the data has been classified, the policy can decide what happens to each element.
For example, a customer support workflow might allow the model to see the product name and complaint while masking the customer’s identity. A financial analysis workflow might preserve transaction values but remove account numbers. A coding workflow might allow source code while stripping credentials and secrets.
The same document can therefore produce different masked output depending on who is using it and what they are asking the AI to do.
That is closer to how enterprises actually use data.
Building an AI DLP Control Layer
The architecture can sit between enterprise data and the AI model.
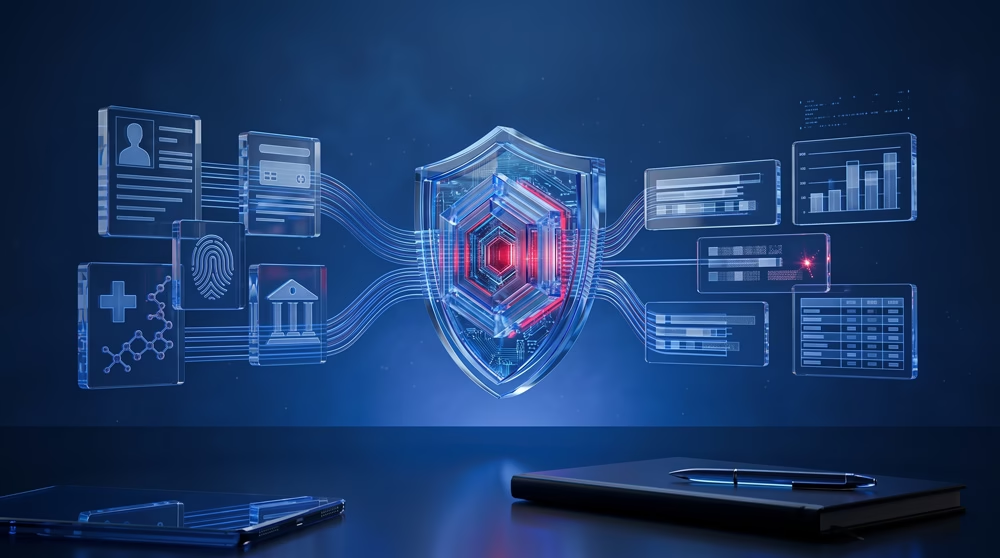
A user interacts with an AI application, but the request passes through an AI DLP control layer before it reaches the model. That layer can inspect the content, identify sensitive information, apply the relevant policy and then mask, tokenise, remove or allow specific data.
The model receives the processed version rather than the original data.
The response can then pass through another inspection stage before it reaches the user or an enterprise application.
This creates two important control points.
The first is before the model receives the data. Sensitive information can be reduced at this stage.
The second is after the model produces its response. The output can be inspected for sensitive information before it is returned or used elsewhere.
The control layer should ideally be independent of the model provider.
An enterprise might use Microsoft Copilot for productivity, ChatGPT Enterprise for analysis, Gemini for specific workflows, Claude for development and internally hosted models for sensitive applications.
The organisation should not need a completely different DLP policy for each one.
A policy such as “customer identifiers must not be exposed to external foundation models unless the workflow is approved” should apply regardless of which provider handles the request.
RAG Makes the Boundary Even Harder to See
The obvious example is someone pasting information into ChatGPT or another AI assistant.
Enterprise AI is increasingly doing something different.
The user asks a question. The application retrieves information from SharePoint, a CRM, a service management platform, a data warehouse or an internal knowledge base. That information is then placed into the model’s context.
The user never uploaded the sensitive document.
The model still received it.
This is particularly relevant to RAG implementations because retrieval can bring much more information into a model context than the user intended.
A customer service assistant might retrieve an entire customer record when it only needs the product history.
An internal HR assistant might retrieve a personnel document containing salary information when the user’s question only concerns leave policy.
A security assistant might retrieve raw logs containing session tokens when the analysis only requires event types and timestamps.
Putting DLP at the chat interface does not solve that problem.
The inspection point needs to exist between retrieval and the model.
The retrieved content can be inspected, sensitive fields can be removed or masked, and only the required context can be passed to the model.
The model should receive the minimum useful representation of the retrieved information.
That is effectively least privilege applied to model context.
Agents Turn Data Access Into an Ongoing Problem
AI agents make this harder because they can keep retrieving information and taking actions throughout a workflow.
An agent might read an email, look up a customer in the CRM, check an order, search an internal knowledge base and then create a support ticket.
Every one of those steps can introduce new information into the model’s context.
Giving the agent access to a system does not mean the model should receive every field that system can return.
That distinction needs to exist in the architecture.
An agent handling customer support might need a customer ID to retrieve an account. It may not need the customer’s personal email address in its reasoning context. It might need an order number to check a transaction but have no reason to receive payment credentials.
The same applies to actions.
A model that can read a CRM should not automatically be able to export customer data. A model that can search a mailbox should not automatically be able to send an email containing everything it found.
Data masking, retrieval filtering and tool permissions need to work together.
The Masking System Becomes Sensitive Data
There is a less obvious problem with reversible masking.
If [CUSTOMER_ID_001] maps back to 78451236, someone has to maintain that relationship.
That mapping is sensitive.
A compromise of the token store could potentially expose the relationship between the protected values and the original information. It therefore needs its own access controls, encryption, tenant isolation, retention rules and monitoring.
The model should not have direct access to it.
Ideally, the model works entirely with the masked representation. Re-identification happens only in a controlled application workflow when there is a legitimate reason to restore the original value.
That separation matters particularly for regulated environments.
The purpose of masking is to reduce what the model knows. Giving the model a mechanism to reverse its own masking defeats much of that benefit.
DLP Still Needs to Inspect the Output
There is another side to the transaction.
Even when the input is controlled, the model can produce sensitive information in its response.
It may reproduce information retrieved from an internal system. It may include a sensitive value from the original context. An agent may generate a support ticket or email containing information that should not leave the controlled environment.
That makes output inspection part of the same architecture.
The response can be checked against DLP policies before it reaches the user or another system. Depending on the policy, the system can allow the response, remove a sensitive value, replace it with a masked representation or block the action.
Input inspection reduces unnecessary exposure before the model sees the information.
Output inspection reduces the chance of sensitive information leaving the AI workflow.
Prompt Injection Is Still a Separate Problem
Masking reduces data exposure. It does not make an AI application trustworthy.
A document retrieved by an AI assistant can contain instructions designed to manipulate the model. An email can contain malicious content. A webpage can attempt to influence an agent into revealing information or using a connected tool.
Prompt injection is therefore a separate control problem.
The AI DLP layer should limit what information reaches the model, while application controls determine what instructions can be trusted and what actions the model is allowed to take.
Identity, authorisation, retrieval permissions, tool restrictions, output validation and monitoring still have to be in place.
AI data masking is useful because it addresses one specific problem well: how much sensitive information should the model receive in the first place?
A New Control Layer for Enterprise DLP
The traditional DLP question has been fairly straightforward:
Can this information go there?
AI introduces a more useful question:
How much of this information needs to go there?
That distinction gives security teams another option between allowing an entire transaction and blocking it.
A developer can use an AI coding assistant without sending credentials along with the source code.
A finance team can analyse customer data without exposing every customer identifier.
A support team can use AI to work through complaints without giving the model the identity information contained in every record.
A RAG application can retrieve internal documents while filtering sensitive fields before they enter model context.
An AI agent can work with enterprise systems without inheriting every piece of information those systems contain.
None of this removes the need for traditional DLP.
It extends it.
Enterprise AI is creating a new place where sensitive data needs to be controlled: inside the information being prepared for the model itself.
That is where AI data masking fits.
It can sit between enterprise data and AI systems, reducing unnecessary exposure while keeping enough context for the model to perform useful work.
For organisations building AI into business processes, that is becoming a practical DLP control rather than a theoretical security feature.